Foundation guide · AI. Large language models generate text by computing which tokens fit a context. Their abilities emerge from training and from the systems built around them, including retrieval, tools and evaluation. Understanding how large language models work helps explain why they can write useful drafts, adapt to instructions and still produce statements that require checking.
This guide follows a request from input to output. It separates what a model learns during training from what an application supplies at run time, then explains how to investigate claims about memory, reasoning and accuracy. It describes common designs; individual models and products can use different architectures and workflows.
Start with tokens, parameters and context
Tokens are the units processed by the model
Text is represented using tokens, which may correspond to whole words, word pieces or other character sequences. A language model assigns probabilities over possible continuations given its context. Google’s introduction to large language models explains this prediction task and the use of numerical representations for language.
The distinction matters when a product advertises a context limit. A token is not universally equivalent to one word, and the limit may be shared among instructions, documents and generated text. For a long-document task, check what information actually entered the request rather than assuming the application’s visible file list was fully processed.
Parameters are different from conversation history
Parameters are values learned during training. Context is information supplied for a particular computation. Adding a paragraph to a prompt changes the context; it does not ordinarily retrain the model. A product may separately save preferences or retrieve past messages, but that is an application feature that needs its own description.
Consider a fictional assistant asked to summarize a report. It may receive the full report, selected passages or a search result. Those are different inputs even if the chat window looks identical. When assessing an answer, determine which information the model had available.
What transformers contribute
The 2017 Attention Is All You Need paper introduced the Transformer architecture, organized around attention mechanisms. Attention allows representations to combine information from different positions in a sequence. This is a computational relationship, not a claim that the model attends in the human psychological sense.
For an intuitive example, compare “the crane lifted the beam” with “the crane stood in the marsh.” The surrounding words help identify which meaning is relevant. The example illustrates why relationships among tokens matter; it is not a literal account of a particular model’s internal decision.
Architecture is only one part of the explanation. Training data, objectives, model size, post-training and inference settings also shape behavior. A headline that credits every improvement to “a new transformer” should explain which component changed and how the contribution was tested.
Pretraining and instruction-following
Broad training establishes language capabilities
The Language Models are Few-Shot Learners paper studied how a large pretrained model could perform tasks from instructions and examples in its context without task-specific parameter updates. It is a useful historical reference for distinguishing learning during training from adapting behavior within a prompt.
In-context examples can show an output format or demonstrate a task. Suppose you provide three examples of converting meeting notes into action lists. The model can use those demonstrations while generating a fourth list. That does not establish that the behavior will persist in another conversation or that the model has permanently absorbed the examples.
Post-training changes how a model responds
Training language models to follow instructions with human feedback describes a pipeline using demonstrations, comparisons of outputs and further optimization. The goal included making responses more aligned with instructions. It illustrates why a base language model and an assistant built from it can behave differently.
However, a preference for one answer is not identical to a direct test of every factual claim inside it. In a product evaluation, ask separately about instruction-following, factual support and task completion. A polished response can be easy to read while still needing correction.
Retrieval adds information at answer time
The original retrieval-augmented generation paper combines a generative model with access to retrieved documents for knowledge-intensive tasks. The important distinction is that some information comes from an external collection rather than only from the model’s learned parameters.
In a document assistant, retrieval could search a folder for passages relevant to a question. Generation then uses those passages to compose an answer. Each stage creates a separate check: was the right passage retrieved, was it current, and did the answer represent it accurately?
A citation does not eliminate these checks. Open it. A correct link may lead to a document that does not support the sentence next to it. A source may also contain an exception omitted from the answer. For important summaries, compare the conclusion with the relevant section of the document.
Tools extend the workflow
A calculator and a model play different roles
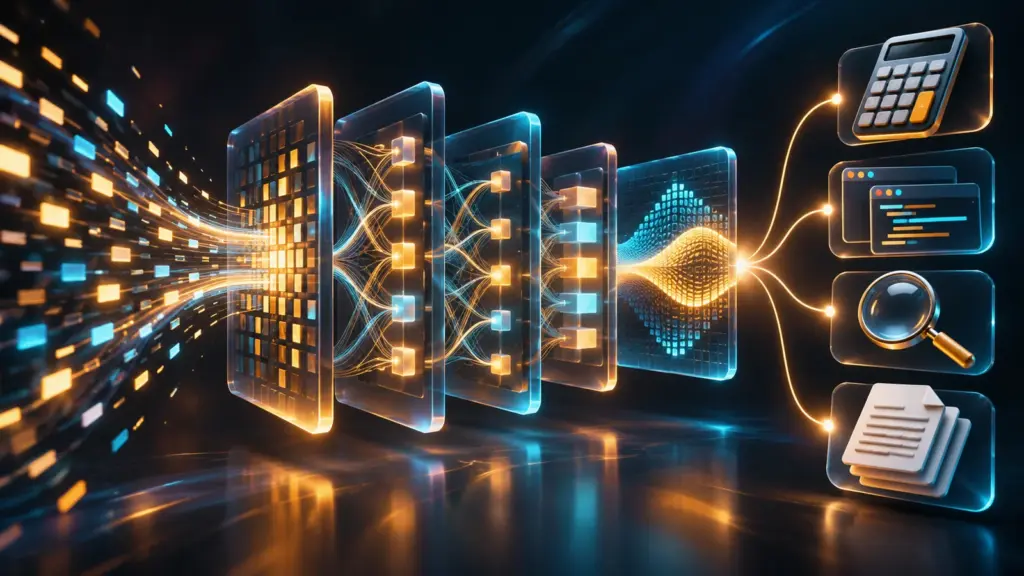
Imagine an application that lets a model request a calculation. The model proposes an operation, software runs it, and the result returns to the conversation. A correct calculation can still answer the wrong question if the model selected the wrong numbers or units. Verification needs to cover the inputs and interpretation, not only the arithmetic.
Similarly, a browsing tool can provide a current page, but the final response may summarize it poorly. It is useful to think in stages: request, retrieved evidence, tool result and final interpretation. This makes errors easier to diagnose than treating the entire assistant as one indivisible capability.
Action permissions belong to the application
A system that drafts an email and one that sends an email have different operational consequences. When a report describes an “agent,” look for the tools it can call, its permitted actions and the conditions under which a person intervenes. The label alone does not establish how independently the system operates.
A request-to-response walkthrough
Consider one task: “Find the renewal date in our policy file and draft a reminder.” The visible answer may look like one operation, but a production application can perform several distinct steps.
- Instruction assembly: the application combines the user’s request with system rules, role information and output requirements.
- Retrieval: a search component locates likely passages in the policy file and places them in the model’s context. The base model does not inherently possess the current private file.
- Generation: the model predicts an answer from the assembled context. It may quote the date and draft the reminder, but the text still needs to be checked against the retrieved passage.
- Tool use: if the application can create a calendar item or send mail, it translates a proposed action into a tool call. Permissions and argument validation belong to the application.
- Guardrails and review: software rules or a person can reject an unsupported date, require a citation or demand confirmation before any external action.
- Storage: the product may save the conversation or selected details. Persistent memory is a product feature with its own controls; it is not a property shared by every language model.
This separation matters when a demonstration succeeds or fails. Retrieval, tools, guardrails and memory can improve an application, but they should not be described as inherent capabilities of the base model. Diagnose the component that supplied the evidence or performed the action.
Why plausible text can be wrong
Language generation and factual verification are different tasks. FActScore evaluates factual precision by breaking long-form responses into smaller claims and checking support against a knowledge source. This research provides a useful reading lesson: an answer can contain both supported and unsupported statements.
For example, a fictional biographical answer might correctly name a person’s occupation while inventing an award. Calling the entire answer “accurate” would conceal that distinction. When evaluating a factual assistant, decide which claims matter and how they will be checked before admiring the overall fluency.
Our AI benchmark guide explains why answer scoring, task selection and evaluation conditions should accompany any accuracy claim.
A worked example: summarizing a long report
Suppose your task is to identify the conditions attached to a fictional research grant. Start by specifying the document version and the exact output: a list of eligibility conditions with page references. Provide or retrieve the relevant document rather than relying on a general question about the grant’s name.
Inspect whether the assistant distinguishes required conditions from recommendations. Check dates, exceptions and definitions. If a condition is absent from the answer, establish whether the passage was missing from the input or overlooked during generation. That distinction points to a different remedy.
Finally, compare the result with a manually prepared answer for a small set of representative documents. Include a report with confusing formatting and one with an important exception. This creates a test of the workflow you need, rather than an impression based on one successful conversation.
Diagnose the failed step before changing the system
Return to the report-summary example. If the correct paragraph never reached the model, extending the answer length is unlikely to address the main problem. Investigate document extraction and retrieval. If the paragraph was present but its exception was omitted, focus on the generation task and evaluation. If the answer was correct but the displayed link pointed elsewhere, inspect the citation-handling layer.
This distinction also helps interpret product updates. A release could improve search, increase accepted input length or change the model. Each may improve the user experience, but they are different changes. A comparison should say what was held constant and what was modified.
Keep a simple failure log with the input, expected result, observed result and suspected stage. Treat the suspected stage as a hypothesis to test. Repeating the same prompt until a correct answer appears shows variability; it does not establish that the original issue has been resolved.
For a factual workflow, also distinguish unsupported claims from explicit uncertainty. An answer that says the document does not provide a value may be correct. A scoring system that rewards a filled field in every case could encourage exactly the behavior you want to avoid. Include examples where the appropriate answer is that the source does not establish the requested fact.
Questions readers often ask
Does a longer context guarantee better answers?
No. Capacity tells you how much input a configuration accepts, not whether every relevant detail will be used correctly. Test the required task and inspect the supplied material. Adding irrelevant documents can also make it harder to identify what actually supported the answer.
Does a model browse the internet automatically?
That depends on the surrounding application and the tools enabled for the request. Distinguish a generated answer from one based on retrieved pages. The interface should make the source of current information understandable.
What should I read next?
Use our AI overview for the broader vocabulary, then compare evaluation claims and the infrastructure required to serve models. Keeping mechanism, evidence and resources separate makes new product announcements easier to assess.
Sources and method
This guide draws on original technical literature, including the Transformer paper, and documentation linked in the text. The walkthrough is a fictional teaching example designed to separate model behavior from retrieval, tools, permissions, review and storage.
Reviewed and updated October 6, 2026.